01 / THE PROBLEMCan a video model search less history without throwing it away?
Selecting only a few KV entries does not automatically make streaming attention cheap. Exact Top-k still scores the complete causal history for every new visual query, so the search becomes more expensive as video accumulates. Discarding old entries reduces storage, but can remove evidence needed by a later question. TaRo targets the repeated search while retaining that history.
02 / THE APPROACHReuse candidates, recompute the decision
01Keep a bank for each visual-token position
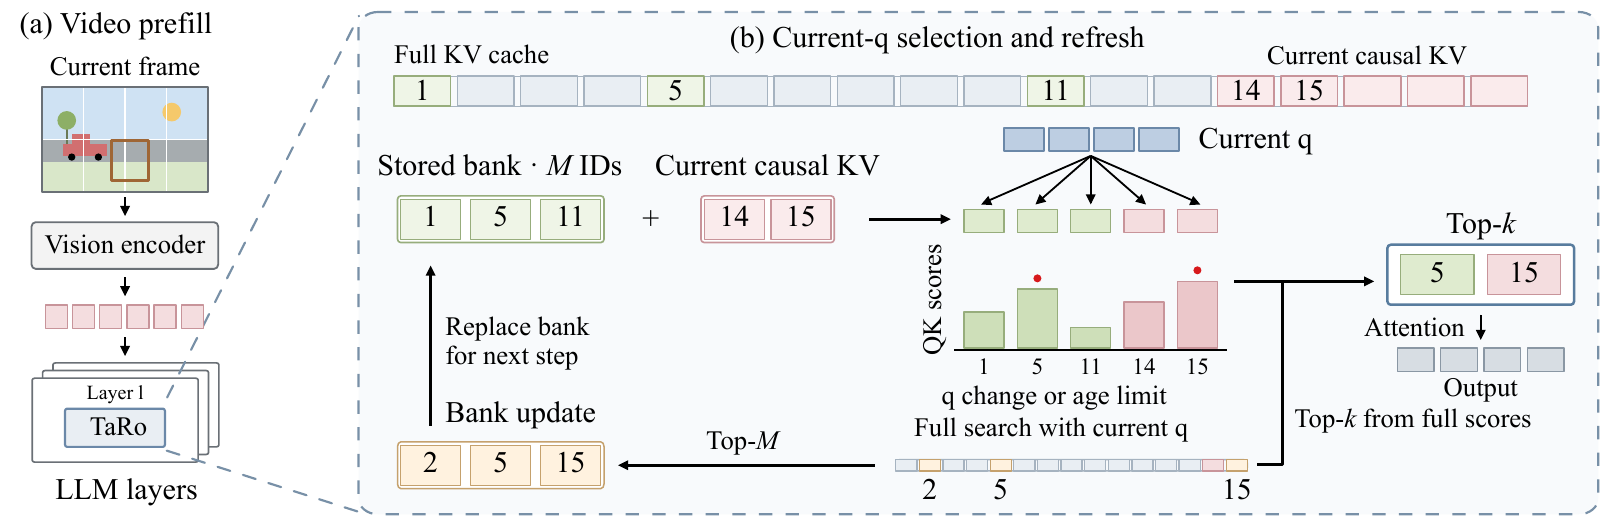
Corresponding positions in consecutive video frames often produce similar queries. TaRo uses that continuity to maintain a small bank of promising historical key indices for each layer, query head, and visual-token position. The bank stores indices; the complete keys and values remain in the KV cache.
Rescore with the current frame
For each new query, gather keys from the bank and the current frame’s causal KV entries. Recompute their scores, select the final Top-k entries, and perform attention. The selected set can change on every frame even when the candidate bank is reused.
Refresh when the query changes or the bank gets old
A drop in query similarity or a maximum bank age triggers a full-history search. That search both serves the current query and rebuilds the bank. Query heads sharing a KV head coordinate refresh decisions, so the policy respects grouped-query attention.
Make the reduced search efficient on the GPU
Fused Triton kernels combine candidate gathering, current-query scoring, selection, and attention. Evaluation includes bank management and refresh work, so the reported latency reflects the cost of maintaining reuse as well as the work it avoids.
03 / MY CONTRIBUTIONMethod design and GPU implementation
As first author, I designed the candidate-reuse method and refresh policy, implemented fused Triton kernels for gathering, rescoring, selection, and attention, and evaluated two video-language models on an NVIDIA H100.
Temporal reuseKV candidate banksTriton kernels
04 / EVALUATIONSetup and results
I evaluated LLaVA-OneVision-0.5B and Qwen2.5-VL-3B on an NVIDIA H100 80 GB in BF16, using matched video prefixes from OVO-Bench and StreamingBench subsets. The main configuration keeps 512 candidates and selects 128 entries for attention. Comparisons include ReKV, Exact Top-k, and Dense attention.
- LLM-prefill speedup
- 1.37–3.58×
- Versus ReKV across the evaluated model and context-length settings.
- Lower Vision+LLM latency
- 30.6–31.0%
- For LLaVA, including vision encoding and video prefill, versus ReKV.
- Early-to-late latency growth
- 2.7–4.9%
- On fixed evaluated video sets; Exact Top-k grew by 38.9–99.1%.
05 / OUTCOME & SCOPELess repeated search as history grows
Accuracy changes relative to ReKV range from −4.60 to +6.59 percentage points across model–benchmark settings. The main speedups measure video prefill; question processing and answer generation are outside that timing scope. TaRo retains the full KV cache and adds candidate-bank state, so its benefit is reduced search work rather than reduced KV-cache capacity. The evaluated histories reach approximately 32K entries for LLaVA and 16K for Qwen.